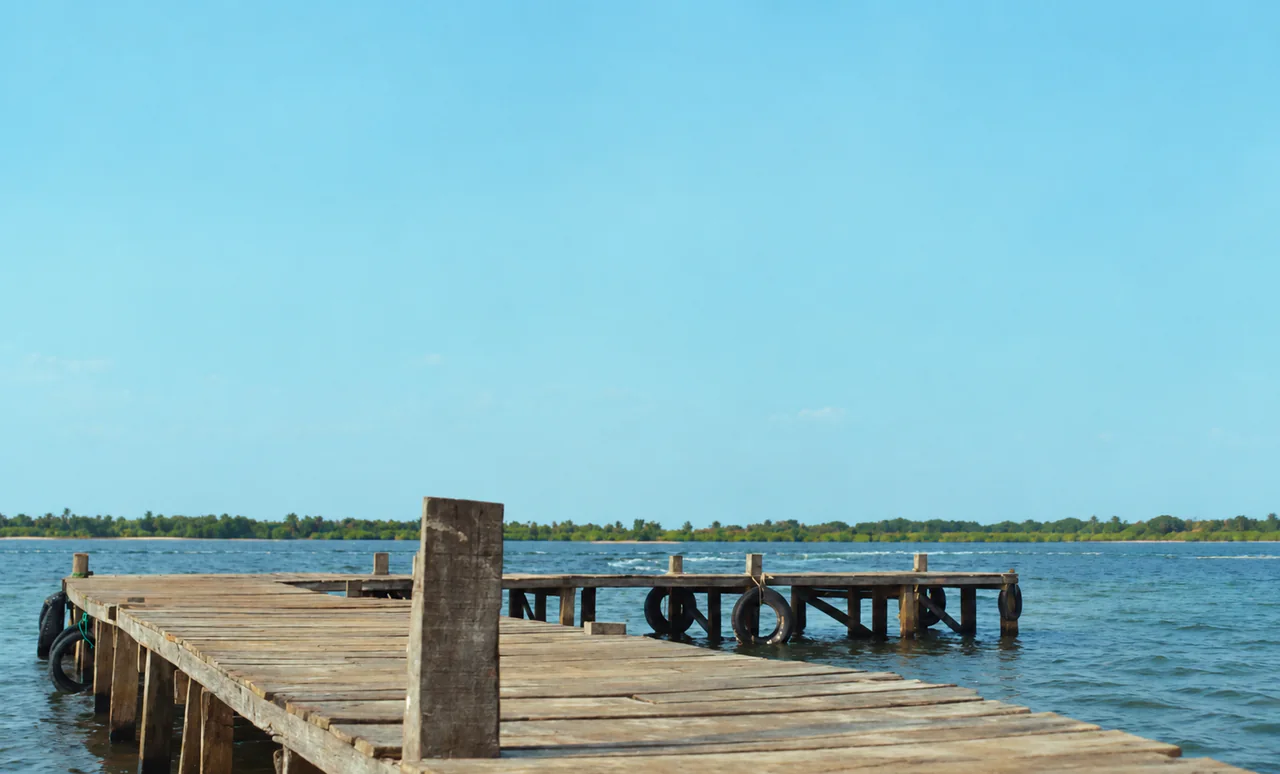
Raindance AI: The Trend, the Technology, and How to Make a Convincing Two-Person Video
Learn the Raindance AI trend, compare 15s and 28–29s versions, make a two-person video, fix role swaps, and understand costs, audio, and permissions.
Updated October 7, 2026
Raindance AI is a music-video remake trend in which new people, pets, or fictional characters take part in a waterfront performance associated with Dave and Tems’ “Raindance.” The recognizable setting and performance stay familiar; changing the cast creates the personal moment or the joke. Published tutorials show both direct edits of the reference sequence and newly generated interpretations of its visual style.12
The effect is easy to recognize but more demanding to make than a moving portrait. A convincing version needs two distinct identities, believable movement, consistent appearances across camera cuts, and music that lands at the right moment. A beautiful face in one frame is only the beginning.
This guide explains the trend’s origins and appeal, the difference between short and full-sequence versions, how the technology works, and how major model families approach the task. It also covers photographs, prompts, creative variations, common visual problems, sound, cost, and responsible publishing.
The central creative decision is whether to preserve an existing performance or create a new one. For a close remake, choose a two-person recasting or reference-video editing workflow. For an original interpretation, choose multi-reference generation. Those approaches can produce equally attractive videos, but they solve different problems.
1. What is the Raindance AI trend?
The waterfront version is a form of AI recasting: a familiar performance is presented with a different cast. Instead of filming on a pier, directing two performers, and recreating a sequence of close-ups and shared shots, a creator supplies character references and works from an existing visual structure.
The scene is important. A recognizable location, an entrance, a performance toward the camera, and the relationship between two subjects give the format its identity. Simply generating two people near water does not necessarily reproduce the effect that prompted someone to search for “Raindance AI.”
There are three useful categories:
| Type of video | What stays recognizable | What changes |
|---|---|---|
| A reference-based remake | The source performance, framing, and sequence | The people or characters playing the two roles |
| An original scene inspired by the trend | The music-video mood and two-person concept | The location, gestures, camera work, or story may be newly generated |
| A conventional music-backed edit | The song and editing rhythm | Existing photos or clips are arranged without necessarily generating replacement performers |
These are creative categories rather than product labels. A service may use “template,” “motion transfer,” or “AI video” for more than one of them. The preview is often more informative than the name: does it promise the same performance with a new cast, or merely a similar-looking scene?
Raindance AI is not one universal model
In this context, “Raindance” names the song and the visual trend, not a single AI engine. A model creates or edits the frames; an application organizes the workflow; a template supplies a prepared scene and instructions. Several different combinations can produce a Raindance-style video.1
That distinction matters when comparing results. A carefully prepared template can be easier to use than a general-purpose model even when both rely on similar underlying technology. Conversely, an advanced editor may offer far more control than a one-click template, at the cost of more preparation.
It is not necessarily a video of people dancing in rain
For the Dave-and-Tems remake, the useful visual references are the waterfront setting and the performance—not literal rainfall. “Rain dance” can also describe unrelated rainy-street or weather-themed videos. Check the reference before selecting a tutorial or writing a prompt.
The Raindance filmmaking organization and film festival are another separate subject. Neither that search intent nor generic rain effects should be confused with this music-video recasting format.1
2. The original song and music video
The recording is “Raindance,” credited to Dave and Tems. Apple Music lists it on Dave’s The Boy Who Played the Harp, released on October 24, 2025, with a track length of 3 minutes 39 seconds.3
Universal Music Canada announced the official music video on January 9, 2026, and identifies Lagos, Nigeria, as its filming location. The announcement links directly to the original video.4
Watch the official “Raindance” music video on YouTube.
The song also reached number one on the UK Official Singles Chart. The Official Charts record lists two weeks at number one and thirteen weeks in the Top 10. Those figures describe the song’s chart performance, not the audience size of the later AI-remake trend.5
The song, the source video, and the AI format have different timelines
| Milestone | Established date or context | Relevance to the trend |
|---|---|---|
| Album release | October 24, 2025 | Establishes the release context of the recording |
| Official music-video announcement | January 9, 2026 | Establishes the source production and its filming location |
| Public AI-remake tutorials and templates | Documented by early October 2026 | Shows that the visual format had become reproducible through multiple workflows |
The first two milestones are documented by music-industry sources. The third is illustrated by dated creator and product tutorials, including Starrd’s October 5 guide.346
There is no verified first AI-remake creator established by these sources. The release of the original video, the first experimental remake, and a later widely shared version should not be treated as the same event.
What does “AI” refer to?
It refers to the remake’s visuals. Using a photograph to replace a performer does not make the original recording an AI-generated song. It also does not automatically clone the photographed person’s voice. Visual casting, musical performance, and audio generation are separate parts of the production.3
3. Why this format is appealing
Raindance works as a creative format because it combines recognition, substitution, and a relationship between two characters. The following analysis concerns the format’s structure; it is not a claim about a platform’s recommendation algorithm.
Familiar structure makes the substitution readable
A recognizable reference gives viewers a baseline. They can understand what has changed without needing an explanation of the production process. The music, location, and shot pattern establish the scene; the new cast becomes the reveal.
This is different from a wholly unfamiliar generated video. In an original scene, the viewer must understand both the world and the characters. In a remake, the familiar performance can carry some of that work. The novelty is concentrated in a clear question: who is playing these roles now?
Two subjects create more possibilities than one
A single animated portrait can show likeness and movement. Two subjects can suggest friendship, romance, rivalry, an unlikely partnership, or a joke about their relationship.
That changes the creator’s task. Selecting two individually recognizable figures is not enough; the pairing should make sense to the intended audience. Two original mascots with opposite personalities, for example, can create a clearer idea than two unrelated designs chosen only because they look elaborate.
The most useful creative question is not “Which two images can the model accept?” It is “What does this pairing communicate when it appears in this performance?”
The original performance supplies more than movement
A reference can carry the timing of an entrance, the pause before a look, the contrast between a wide shot and a close-up, and the rhythm of the edit. Those details give the result a directed quality.
This explains why a visually polished remake can still feel wrong when the model changes the timing. A gesture performed a little later may no longer land with the music. A replaced close-up may look excellent while the sequence loses the interaction that made the original compelling.
The same format supports sincerity and humor
A couple’s version can use the waterfront scene as a personal keepsake. A character remix can use the seriousness of the performance to make an improbable pairing funny. The emotional treatment does not have to change; the meaning can change through casting alone.
Public examples illustrate this range. Ala Visuals documents a human-and-humanoid-robot remake. A community gallery presents pairings including Shrek and Lord Farquaad, Gru and Vector, and Ronald McDonald and Colonel Sanders. These are examples of creative directions, not a ranking of audience preferences.27
Participation shifts from filming to creative direction
The prepared performance allows someone to focus on cast, visual design, and editing rather than recreating the physical shoot. Two people do not need to have been photographed together to appear in the same generated scene; separate uploads are supported by published two-person templates.8
The remaining craft is still substantial. References need to be suitable. Characters must remain recognizable. The final cut must work as a video rather than as a sequence of attractive stills.
Novelty is only the first layer
Once the substitution is understood, the video still needs a reason to continue. A second-person reveal, a readable interaction, a change of shot scale, or a satisfying final image can provide that reason.
A useful editorial test is to watch without thinking about the software. Is the pairing clear? Does the moment develop? Does the ending feel intentional? These questions apply whether the cast is realistic, animated, romantic, or absurd.
4. The main creative versions of the trend
Different versions place different demands on the technology. Treat the creative concept as part of model selection, not as something added after generation.
| Creative direction | Main attraction | Most important production requirement |
|---|---|---|
| Partners or friends | A personal shared scene | Recognizable likeness for both people, including the less prominent role |
| Fictional or original characters | The surprise of an unexpected pairing | Stable whole-character design rather than facial similarity alone |
| Pets | Familiar animals in a performance setting | Clear anatomy choices and readable interaction |
| Brand mascots | A recognizable visual identity in a music-video format | Consistent colors, shapes, accessories, and appropriate media rights |
| A realistic subject with a stylized character | Contrast between the two visual worlds | Different materials and styles that still share believable lighting |
| A fully reimagined scene | A new interpretation of the mood | Coherent direction rather than exact replication of the reference |
The categories above are a planning framework. They are not promises that every model supports every character type equally well.
Real people: likeness is distributed across the whole appearance
A person’s recognizable appearance includes more than the central face. Hairline, hairstyle, facial proportions, silhouette, and familiar clothing may all matter to the viewer. A result can look plausible without looking like the intended person.
Decide whether the goal is a face substitution or a complete recast. Keeping the original wardrobe can be acceptable for a face-focused version. It is less appropriate when the uploaded outfit is part of the person’s identity in the intended edit.
Pets: choose realism or anthropomorphism
A pet can remain anatomically animal-like, or it can become an anthropomorphic performer. Those are different creative choices. Asking for a real dog’s body while also requiring every human hand gesture creates an unresolved brief.
For an animal-like version, reinterpret the interaction through head turns, sitting, stepping, and body orientation. For an anthropomorphic version, define a coherent character design before animating it. Neither choice is automatically better; consistency makes the decision readable.
Robots and stylized characters: the body is part of the identity
A robot’s joints, shell, head shape, and proportions may be more important than a human-like face. A cartoon character may depend on a silhouette or color pattern that disappears if it is translated into generic realism.
Use references that show those properties. Do not request photorealistic skin as a blanket instruction when one subject should remain metallic, illustrated, or plush. The scene can share a consistent lighting treatment without forcing both characters into the same material.
5. Fifteen seconds or twenty-eight to twenty-nine seconds?
Both shorter edits and longer versions are in use. Available examples do not establish a universal winning duration.
Published references provide a useful distinction:
| Public example | Stated length | What the number describes |
|---|---|---|
| Nsketch’s Rain Dance template | 15 seconds | A template’s output length |
| Starrd’s Raindance guide | 28 seconds | A described finished edit |
| Hotel Lobby AI’s Tyler community gallery | 29 seconds for each of three examples | The gallery’s labels for independently created remakes |
The gallery explicitly distinguishes its community examples from videos generated by its own product. Its selected examples and duration labels are not a representative measurement of the highest-performing social posts.867
Four lengths are easily confused
The song is the full recording. The reference excerpt is the section used as visual guidance. A generation is the clip a model produces in one operation. The finished edit is the assembled video viewers watch.
A longer edit may combine shorter generations. A shorter edit may use only the strongest part of a longer source. Consequently, a model’s maximum duration does not define the trend’s duration.
Likewise, the difference between twenty-eight and twenty-nine seconds can come from trimming or an ending hold. Check the actual sequence rather than assuming that nearby duration labels refer to identical content.
Choose the length around the reveal and the payoff
A compact version works when it establishes the setting, reveals both subjects, and reaches a satisfying moment without unnecessary repetition. A longer version earns its length when additional shots develop the interaction or give each character a meaningful appearance.
The key is not to remove the second subject’s payoff while keeping a long opening. In a duet, a short edit that barely shows one participant can feel incomplete even when its pacing is fast.
Plan the ending too. A shared final shot, a completed gesture, or a musical resolution can make the edit feel deliberate. Extra seconds of a frozen frame are not equivalent to extra performance.
For comparison, assess different cuts using the same cast and musical section. A fifteen-second version of one idea and a twenty-eight-second version of a different idea do not isolate the effect of duration.
6. How the effect works: separating cast from performance
A reference-led remake can be understood as five coordinated tasks: identifying the intended cast, interpreting the source performance, mapping each new subject to a role, generating the changed appearance, and maintaining continuity through time.
This is a conceptual explanation of the job. Individual systems implement it differently; a product does not necessarily contain five separate components.
Appearance references answer “who?”
The uploaded images specify what the replacements should look like. A portrait emphasizes facial identity. A full-body reference supplies more information about clothing and proportions. A coherent character sheet can describe a design from several angles.
The references should remain separate in meaning even when a workflow combines them into one preparation stage. The output needs two distinct subjects, not an average of their features.
A photograph also has limits. Unseen details—such as the back of a jacket or a character’s hidden mechanical structure—are not recovered simply because the final video is detailed. They must be supplied, intentionally designed, or generated as an interpretation.
The source video answers “what happens?”
The reference carries movement, relative positions, framing, shot transitions, and timing. These are separate from the original performers’ identities.
Modern multimodal video systems explicitly distinguish these roles in different ways. H3’s published system description includes image, video, and audio references; Seedance 2.5 emphasizes reference control and editing; Kling’s Omni guide describes combinations of reference images, video, and character elements.91011
The practical implication is simple: the same source can guide the performance while separate images define the cast. However, the source still contains the original cast’s visible appearance, so the system must decide which information to preserve and which to replace.
Role mapping answers “who replaces whom?”
Two reference images do not automatically explain the intended assignment. The original man and woman, the singer and partner, or two clearly identified source characters need stable roles.
Temporary position is a weak identity description. Someone who begins in the background may later occupy the foreground. Someone sitting at the beginning may stand, move, and re-enter. The assignment should follow the original person, not the current location of a body in the frame.
This is why a two-person remake is more than two independent face edits. The relationships among reference identity, source role, and screen position must remain distinct.
Generation must integrate the new appearance into the scene
A convincing replacement needs appropriate scale, perspective, illumination, and contact with the environment. Hair must fit the movement. Clothing must respond plausibly. A changed body design must still interact with the pier, nearby objects, and the other performer.
There is a creative trade-off here. Preserving the source very closely can also preserve unwanted traces of the original appearance. Allowing more reconstruction can make a radically different character fit, but may change the framing or motion. The best balance depends on whether the brief values exact source fidelity or a more ambitious redesign.
Continuity has two levels
Within-shot continuity keeps a character coherent as it turns, moves, or is partly hidden. Across-shot continuity keeps it recognizable when the camera cuts to a new angle, distance, or lighting context.
A system can succeed at the first and fail at the second. A face may remain stable through a single turn yet become a different interpretation after a cut. Conversely, separate close-ups may look convincing while a shared shot reveals duplicated features or incorrect assignments.
That is why the complete sequence—not a single frame—is the appropriate unit of quality.
7. How major models and editing systems approach Raindance-style video
The useful comparison is between creative capabilities and control strategies, not between model names alone. The following analysis draws on official model descriptions and published production workflows. It identifies task fit rather than claiming a measured, universal quality ranking.
| Model or creative system | Documented emphasis | Where that emphasis matters for this effect |
|---|---|---|
| ByteDance Seedance 2.5 | Longer multi-shot generation, multimodal references, structural guidance, and targeted editing | Building a fuller sequence around two cast references and a detailed performance plan1012 |
| MiniMax H3 / Hailuo, including H3 Max Recast | General multimodal reference generation; a separately documented people-recasting workflow | Distinguishing a broad creative remake from a source-preserving change of cast913 |
| Kling VIDEO 3.0 Omni | Multi-image and video references, reusable character elements, and storyboard control | Organizing persistent character identities across several views and shots11 |
| Google Gemini Omni | Conversational video editing, reference-guided changes, and iterative refinement | Directing revisions while retaining the context of an existing scene14 |
| Higgsfield Genjutsu | Motion Transfer and Object Swap as distinct creative workflows | Choosing between reconstruction around a performance and a more selective visual change15 |
| Runway Aleph 2.0 | Edited-frame guidance, selective changes, and multi-shot propagation | Approving the intended visual change in a frame before carrying it into the video16 |
Genjutsu is listed as a creative system, not as a claim about its undisclosed underlying foundation model. Similarly, a dedicated recasting workflow should not be assumed to behave identically to every general-generation mode within the same model family.
Seedance 2.5: longer sequences and structural control
ByteDance describes Seedance 2.5 as supporting up to thirty seconds in one generation, expanded multimodal referencing, and timestamp-level audio-video editing. Its release material also discusses clay-render guidance for composition and blocking, while acknowledging remaining challenges in complex motion and multi-subject interactions.12
For Raindance, the attraction is the ability to treat the video as a sequence rather than a collection of unrelated short clips. A source or structural reference can establish the movement while cast images provide appearance. That makes it relevant to a full duet with shared shots and individual close-ups.
The distinction to watch is reconstruction versus preservation. Strong reference-led generation can produce a coherent interpretation without reproducing every source frame exactly. Creators should decide how much variation is acceptable before treating a more cinematic result as a more faithful one.
Task-fit assessment: a strong candidate for planned multi-shot remakes and structural-reference workflows, particularly when the cast or visual design changes substantially.
MiniMax H3 and H3 Max Recast: general reference generation versus recasting
MiniMax’s published H3 system supports multimodal references and four-to-fifteen-second outputs. Its documented architecture combines context interpretation, base generation, and a separate high-resolution regeneration stage. That makes the complete workflow relevant, rather than output resolution alone.9
H3 Max Recast is documented separately as replacing people from reference photographs while preserving source motion, camera behavior, cuts, and sound. The published workflow takes one photograph per replacement person and can specify the intended assignments; it accepts source videos of five to thirty seconds, with no individual shot longer than fifteen seconds.13
These are meaningfully different creative propositions. A general reference workflow can reinterpret a scene. A dedicated recasting operation is framed around preserving a performance while changing its cast. A demonstration of one should not be used as proof of the other.
Task-fit assessment: dedicated recasting is especially relevant to human-to-human substitution. Broad claims about arbitrary animals, robots, or radically different anatomy require separate evidence.
Kling VIDEO 3.0 Omni: reusable characters and reference organization
Kling’s official guide describes multi-image elements, video-based character references, combinations of multiple elements, and multi-shot direction. It positions those features around keeping characters recognizable across scenes and camera changes.11
The production value is clear: a character can be treated as a reusable reference asset rather than repeatedly described from scratch. For creators developing several related remakes, consistent reference organization can be as important as the wording of any one prompt.
The important distinction is between character consistency in generated scenes and complete replacement of the correct source performers. The first is necessary for the second, but not sufficient. An attractive recurring character is not a successful duet remake unless it occupies the intended role throughout the source sequence.
Task-fit assessment: suitable for creators who want structured character references and multi-shot direction, with explicit attention to both source-role assignments.
Gemini Omni: conversational control and revision
Google DeepMind presents Gemini Omni as a video-generation and editing system that accepts different reference types, supports character or object changes, and allows a scene to be refined through successive natural-language edits.14
That approach is relevant when the creative brief evolves. A creator may approve the casting, then refine an outfit, adjust the setting, or correct part of a shot. The appeal is the ability to express an intended change in the context of an existing result instead of rebuilding the brief each time.
For a faithful music-video remake, each revision still needs a clear boundary. Fixing a hairstyle should not silently alter a musical gesture or a camera cut. Revisions should be judged against the approved sequence, not only against the most recent instruction.
Task-fit assessment: particularly relevant to iterative creative editing. The official positioning does not establish a Raindance-specific ranking for dance fidelity or two-person success rates.
Higgsfield Genjutsu: deciding how much of the scene to rebuild
Higgsfield distinguishes Motion Transfer, which uses an existing performance to drive a new character or scene, from Object Swap, which targets a specified element while preserving the surrounding footage.15
For Raindance, that distinction is more useful than a general claim of “character replacement.” A complete redesign may benefit from a performance-led reconstruction. A close remake may prioritize preserving the original scene. The chosen mode should match that intention.
Ala Visuals’ published Raindance tutorial uses two multi-view character references with a source video, illustrating how character preparation contributes to the final result.2
Task-fit assessment: relevant to stylized and mixed-character remakes, with the choice between transfer and selective editing treated as a creative decision rather than interchangeable settings.
Runway Aleph 2.0: using an edited frame as visual direction
Runway describes Aleph 2.0 as propagating an edited frame through a video, applying changes across relevant shots, and supporting clips up to thirty seconds at 1080p. Its Edit Studio workflow lets a creator preview a visual change before generating the video.16
For a duet, a prepared frame can make the intended composition concrete: both replacements are already visible in their intended positions. This can be a useful visual brief when text alone leaves too much room for interpretation.
A successful frame does not answer every temporal question. A later profile, an overlap, or a different shot scale may expose details the prepared frame never showed. Visual anchoring and full-sequence consistency are related but separate requirements.
Task-fit assessment: relevant when the desired change can be established clearly in an edited frame, including workflows that place a premium on selective revisions. This is a capability-based assessment, not evidence that it powers a particular Raindance template.
What is the best model, then?
For this effect, there is no defensible one-line answer independent of the brief. A model can be excellent at realistic faces, another at following structure, and another at controlled revisions. A prepared workflow can also outperform an unprepared use of the same model family.
Choose by the hardest requirement: exact people, unfamiliar character anatomy, preservation of the original performance, or a longer coherent sequence. A meaningful comparison asks whether that requirement is satisfied for both subjects throughout the edit.
8. Choose a workflow for the result you want
A model comparison becomes useful only when it leads to a production choice. Start by deciding which aspects of the finished video are negotiable.
| Your priority | Appropriate starting point | What to protect |
|---|---|---|
| An easy personalized duet | A prepared two-person template | Both likenesses, correct roles, complete export |
| The closest version of an existing performance | A dedicated recast or reference-video editor | Actions, timing, camera, and every appearance of both subjects |
| A human paired with a very different character | Multi-reference editing or motion-led reconstruction | Whole-character design, anatomy, and shared lighting |
| A longer, directed music-video sequence | Multi-shot reference generation or a planned shot-based workflow | Character continuity and musical structure |
| A precise change to an otherwise approved result | Selective editing or edited-frame guidance | The parts of the sequence that already work |
| A new story with the same romantic mood | Original multi-reference generation | Coherent casting and direction, rather than exact source matching |
These are selection principles derived from the creative tasks, not measured rankings of individual tools.
Prepared template or general editor?
A prepared template is appropriate when its performance, framing, and character roles already match the goal. The creator is primarily choosing the cast. Look for a preview of the exact template, clear upload labels, and a finished result with both people visible.
A general editor is appropriate when the source, cast design, duration, or final treatment needs more control. It requires more decisions, but those decisions are useful when a template’s fixed behavior would compromise the idea.
Neither is inherently more professional. Professionalism lies in matching the method to the brief and delivering the promised result. An efficient template can be the right tool for a simple duet; a carefully directed multi-stage workflow can be necessary for a more ambitious character transformation.
Direct replacement or reconstruction?
Direct replacement prioritizes continuity with the source. Reconstruction prioritizes creating a coherent new rendering of its performance. They sit on a spectrum rather than forming a perfectly clean boundary.
A realistic person replacing another realistic person may require relatively modest visual change. Replacing a human with a short, wide mascot changes body proportions, contact points, and silhouette. Preserving every original pose literally may be less desirable than preserving the action’s intention and timing.
Write that distinction into the brief. “Follow the performance faithfully” can mean maintaining the exact gesture, or translating the gesture convincingly into a different character’s anatomy. The system should not have to guess which result counts as success.
9. Prepare photographs and character references
Good references reduce uncertainty before animation begins. The goal is not maximum image count; it is a clear, consistent specification of each subject.
Use one intended subject per reference
A group photograph introduces a selection problem. Crop to the intended subject when appropriate, keeping the features needed for recognition. Each role should have a clearly identified reference, even when the two photographs were taken in different places.
Check the face at the size it will matter in the video. Visible eyes, a readable hairline, and a clear head shape are more useful than decorative background detail. Avoid references that hide the most important features behind an object or an extreme angle unless that appearance is intentional.
Match the reference coverage to the brief
For a face-focused remake, a clear portrait may be sufficient. For a complete recast, a waist-up or full-body image can supply clothing and proportion information. A wide shot of a replacement character should not depend entirely on details that never appear in any reference.
Do not assume that a larger file contains more useful identity information. A heavily filtered or blurred image can remain ambiguous at a high resolution. The question is what the image actually shows, not what its dimensions suggest.
Keep the appearance internally consistent
When several references are used for one character, make their purpose clear. Front, three-quarter, and profile views can complement one another. Conflicting outfits or hairstyles create a choice that should be resolved before generation.
For fictional characters, define the important visual rules: silhouette, color palette, head shape, clothing, materials, and distinctive accessories. For real people, prioritize faithful appearance over beautification that changes identity.
Decide whether clothing should change
There are three legitimate briefs: preserve the source outfit, adopt the reference outfit, or design a new outfit. Choose one.
A close face replacement that keeps the original green clothing may be perfectly acceptable when that is the intention. It is a failure when the request is to bring the uploaded character’s entire design into the scene. Clear expectations make evaluation simpler.
Treat generated character sheets as design aids
Additional views generated from one image contain inferred information. Review them before animation. An invented profile repeated consistently is not necessarily a faithful profile.
A useful character sheet preserves the approved identity and clarifies what will be needed in motion. It should not become an excuse to add unnecessary costume changes or visual complexity. The purpose is to reduce ambiguity, not to give the model more competing ideas.
10. How to make a two-person Raindance AI video
Step 1: Select the reference or template
Choose a sequence whose performance and final framing match the intended result. Watch the complete clip, including its ending. Establish whether it is a close remake, an inspired scene, or an ordinary media template.
Use source material you are authorized to process and publish. Keep a clean original so later crops and exports do not become the only remaining version of the reference.
Step 2: Identify the two original roles
For the familiar pier excerpt, the source roles can be described as the original man in the dark-green shirt and the original woman in the pale-green halter-neck dress. Confirm that those descriptions match the chosen excerpt.
Assign a reference to each original person. Do not infer the assignment from the photographed subject’s gender or from where the person happens to stand in a later shot. The original role remains the same when the camera position changes.
Step 3: Prepare the replacement references
Use a clear reference for each subject. Decide whether the video should retain only facial identity or the complete visual design. Check that the supplied images show the details important to that decision.
For a template, follow its upload labels. There is no universal convention that the first photograph is always the singer, the person initially seated, or the first person to appear in close-up.
Step 4: Define the change and the preservation brief
State the two assignments, then specify the source features to retain: action, interaction, timing, framing, camera movement, setting, and lighting. Use the tool’s own reference labels where available.
Avoid adding unrelated scenery or choreography to a faithful-replacement request. Those can be explored as a separate creative variation after the core duet works.
Step 5: Generate a representative sequence
A representative passage should reveal whether both subjects work, not merely flatter the most prominent face. Include a shared shot or a transition between the two roles where the supported workflow allows it.
For a prepared template, inspect the entire returned edit. For a longer production, confirm the casting and visual treatment before committing to additional shots that depend on them.
Step 6: Review casting, continuity, and performance
Watch once for the overall experience. Then follow each subject through the full sequence. Check close-ups, background appearances, turns, overlaps, and the moments immediately after cuts.
A pleasing overall impression should not conceal a missing replacement. A duet requires two correct cast members, not one excellent lead with an unchanged supporting performer.
Step 7: Finish the music and delivery format
Align the authorized soundtrack to the approved edit. Check the musical phrase used by the reference, the timing of any visible singing, and whether the generated file already contains sound.
Create the final crop without losing either subject. Review the exported file from beginning to end, including the last frame and any watermark. Save an approved master before making platform-specific versions.
11. A clear prompt for two-person replacement
The most useful prompt describes the intended operation rather than retelling every movement already present in the source. Its structure is straightforward: source, two assignments, preserved performance, and continuity.
The placeholders below represent the reference labels used by the selected tool.
Recast the two performers in [SOURCE VIDEO].

Use the subject in [REFERENCE A] to replace the original man
wearing a dark-green shirt.

Use the subject in [REFERENCE B] to replace the original woman
wearing a pale-green halter-neck dress.

Keep each replacement assigned to the same original performer
throughout the sequence, including wide shots and close-ups.
Replace both whenever both original performers are visible.

Retain each reference subject's identity and visible character design.
Preserve the source actions, interaction, timing, camera movement,
framing, setting, lighting, and shot transitions.

Keep the two identities separate. Do not exchange their roles,
duplicate either subject, or leave an original performer unchanged.
The descriptions identify the original cast. The uploaded replacements can have different appearances, provided the selected workflow supports them. There is no need to hard-code the user’s hairstyle or clothing into a reusable prompt.
For an original scene, use an original-scene brief
A new performance needs different instructions:
Create a two-character music-video scene starring [REFERENCE A]
and [REFERENCE B] on a wooden pier beside calm water.
Use warm evening light and a relaxed, intimate performance.

Open with both characters visible. Develop their interaction
through a medium shot and a close-up of each. End in a shared frame.
Preserve each character's identity and visual design throughout.
Keep the movement natural and the camera work restrained.
This asks for a new scene. It does not promise the original shot sequence, a specific recording, or exact lyric synchronization.
Add specificity only when it resolves a real choice
Useful additions include whether clothing comes from the reference, whether an animal should remain anatomically animal-like, or whether a stylized character should keep its original materials.
Repeating “perfect,” “exact,” and “never fail” does not resolve those choices. A concise, unambiguous brief is a better starting point than a long list of prohibitions that still leaves the casting or visual treatment undefined.
12. What makes a result convincing?
A strong video balances several kinds of fidelity. They should be evaluated separately because excellence in one area can conceal weakness in another.
| Quality dimension | What a successful result shows | What can look impressive but still fail |
|---|---|---|
| Likeness | Each replacement remains recognizable as its reference | Two attractive but generic faces |
| Assignment | Each reference occupies the intended original role | Both faces are convincing but exchanged |
| Completeness | Both original roles are replaced wherever they appear | Only the prominent subject is changed |
| Temporal consistency | Hair, face, design, and proportions remain coherent through motion and cuts | One excellent still frame |
| Performance fidelity | Gestures, interaction, and musical timing remain appropriate | Smooth movement that changes the action |
| Scene integration | Scale, light, perspective, and contact belong to the environment | A sharp face that appears pasted onto the scene |
| Finished presentation | The edit, soundtrack, crop, and ending work together | A high-resolution file with a broken sequence |
Watch the quieter role
The dominant close-up is not always the most revealing part of the video. A smaller background performer may expose incomplete replacement. A character who reappears after a cut may expose continuity drift. A shared frame may expose identity blending.
At the same time, distinguish a definite failure from insufficient detail. A tiny face may be too small to judge accurately. Look at the broader appearance and later clear views rather than confidently identifying a mismatch that the available pixels cannot establish.
Judge the interaction, not just the bodies
Believable interaction includes eye lines, relative scale, body orientation, and timing. Two individually plausible characters can still seem disconnected if they look past one another or respond at different moments.
For radically different body types, some adaptation may be more convincing than a literal pose transfer. The important question is whether the relationship and action remain legible. Fidelity to the performance’s intention can be the right priority when the anatomy changes.
Presentation quality is not the same as source fidelity
A model may improve the apparent lighting, simplify a background, or invent a smoother camera move. That can help an inspired scene and hurt an exact remake.
Define the acceptable creative freedom before judging the result. Otherwise the most polished output may win a comparison even though it no longer fulfills the original brief.
13. Common visual problems and how to correct them
Most useful corrections are specific: clarify an assignment, improve a reference, change the transformation scope, or revise the affected shot. The remedy should match the visible problem.
| Problem | Likely area to examine | Practical correction |
|---|---|---|
| Only one person changes | Two-person support, reference clarity, or incomplete execution | Confirm both cast references and use a workflow intended to preserve separate subjects |
| The replacements exchange roles | Ambiguous casting or temporary position labels | Map each reference to a clearly identified original performer |
| A character changes after a cut | Cross-shot identity continuity | Reuse the approved references and revise the inconsistent shot |
| The source hairstyle or outfit remains | Appearance preservation is too strong or the brief is unclear | Specify the intended wardrobe and consider a fuller character redesign |
| Both people acquire similar features | References or assignments are not sufficiently separated | Use distinct, coherent references and explicit role descriptions |
| A pet or mascot has broken anatomy | Human pose requirements conflict with character design | Choose a coherent anatomical interpretation and adapt the performance |
| The scene looks right but the timing is wrong | The result is reinterpreting rather than preserving the performance | Prioritize reference-led editing and review the musical sequence |
| The faces are correct but appear detached | Lighting, scale, motion, or edge integration | Revise the shot as a whole rather than sharpening the face alone |
These are diagnostic possibilities, not claims about the hidden internals of a particular model.
When both subjects are not replaced
First make sure the task is actually a two-person recast, not a solo effect with a generated partner. Check both reference previews and the meaning of the two roles. An unclear input or a mismatched template should be corrected before judging the model.
When the brief and references are clear but the result repeatedly leaves one original performer unchanged, a different editing workflow is more meaningful than another paragraph of prompt instructions. The goal is reliable execution, not increasingly emphatic wording.
When a face changes across shots
Compare the inconsistent shot with the approved reference and the neighboring shots. Check whether the problem is facial identity, hairstyle, clothing, or a broader design shift.
Repairing the specific shot can preserve the successful parts of the sequence. The repaired shot must still match its neighbors in appearance, color, timing, and composition. A replacement clip is not finished until it belongs in the edit.
When changing one subject disturbs the other
A selective edit needs to protect the approved character as well as change the target. An extra generation pass can alter the background or the other performer, even when the new target looks better.
Where an editor offers reliable region-based or frame-guided control, use it to constrain the intended revision. Otherwise compare the whole output against the approved version. Do not assume that an unmentioned part of the scene remained untouched.
When higher resolution does not help
More pixels can improve the presentation of a correct result. They do not, by themselves, correct a swapped identity or restore a missing cast member.
Approve the casting and sequence first. Then evaluate whether higher-resolution generation, refinement, or export improves the details that viewers will actually see.
14. Advanced production: character sheets, depth, and visual anchors
More elaborate workflows are valuable when they solve a specific limitation. They are not mandatory steps for every creator.
Character sheets make a design explicit
A multi-view sheet can show an approved face, profile, body, outfit, and back view together. It is most useful when a character’s whole design matters or the source moves through substantially different angles.
Keep the sheet visually coherent. A collection of contradictory views can be less useful than one clear reference. When a generated view introduces a new detail, decide whether to accept that design before asking the video model to preserve it.
Depth guidance emphasizes structure rather than color
A depth map represents the scene’s spatial structure rather than its original surface colors. Depth Anything V2 is a published monocular depth-estimation system; its authors identify it as image-based, so applying it frame by frame is not the same thing as having guaranteed temporal consistency.17
Starrd’s Raindance tutorial describes converting the source to depth, softening original hair and clothing outlines, preparing a multi-view character sheet, and generating with Seedance 2.5 before restoring the song. The reported problem was that untreated outlines carried aspects of the original appearance into the new characters.6
The general lesson is that structure and appearance are not perfectly separable. A dress silhouette is structural information, but it also constrains the apparent outfit. Removing color alone does not remove every trace of the original cast.
A depth-guided remake is therefore a reconstruction strategy. It can make sense when the new character design must differ substantially from the source, but it needs review for motion, contact, silhouette, and continuity.
Edited frames communicate a visual target
An edited frame can show exactly where both new subjects belong and how they should look in the scene. Runway Aleph 2.0 explicitly describes a workflow in which an edited frame guides changes through the video.16
The creative advantage is visual specificity. The limitation is coverage: one frame cannot fully define a subject from every angle or explain how two bodies should behave during an overlap. Good visual anchors complement suitable references; they do not eliminate the need for them.
Shot-based finishing gives difficult moments individual attention
A wide shared shot and a solo close-up pose different problems. A planned shot-based workflow allows each to receive appropriate attention while preserving the intended sequence.
Use actual cuts as natural boundaries where possible. Keep approved character references, color treatment, and musical timing consistent. Pay special attention to the first frame after each join, where a changed face, outfit, or position can make the repair obvious.
The aim is not to create a collection of independently attractive clips. It is to create one coherent performance.
15. Music, lip synchronization, and voice
A Raindance video has three separate audio questions: which recording is playing, whether it is aligned with the edit, and whether the visible performance convincingly matches it.
A visual recast does not automatically generate a new vocal performance. A model with native audio does not automatically return the original song. A file containing the song does not automatically have accurate mouth movement.
Use the correct musical passage
Identify the excerpt associated with the chosen reference. Starting from the beginning of the full song is appropriate only when that is what the edit uses.
Check the musical phrase against camera cuts, gestures, and visible singing. For a multi-part production, one continuous authorized soundtrack can provide a clearer timing reference than several separately generated audio fragments.
Separate lip movement from voice identity
The picture can preserve or reconstruct a performer’s mouth movement while the soundtrack remains the original recording. That is different from voice cloning or generating a cover.
A human close-up makes timing errors particularly visible. Stylized mouths and animal faces require different performance choices, so evaluate intelligibility and expression rather than assuming that one solution applies to every design.
Check whether the file already has audio
Some workflows preserve source sound, while others generate or replace it. H3 Max Recast’s documentation, for example, specifies a recast video with the source sound.13
Avoid accidentally layering the same music twice when moving the clip into a social editor. An offset duplicate can make a visually correct video sound wrong. Review the finished export with sound from beginning to end.
Finally, make sure the music is appropriate to the intended use. Personal sharing, advertising, client delivery, and redistribution inside a downloadable template are not interchangeable permission contexts.
16. Resolution, aspect ratio, and export
The delivery format should preserve the idea. For a two-person performance, that means keeping both subjects visible when their interaction matters.
Do not confuse resolution with framing
A resolution label describes image dimensions or an output tier; an aspect ratio describes the shape of the frame. Neither tells you whether the crop preserves the composition.
A wide source may place the two performers far apart. Cropping its center into a vertical frame can remove one person even when the generated scene is correct. Check each shot rather than applying one crop blindly to the entire sequence.
Possible treatments include fitting the full scene inside a vertical canvas, using a designed border or background, or reframing individual shots. The right choice depends on whether the shared composition or a particular close-up carries the moment.
Keep a master before making social versions
Save an approved version that retains the complete scene and soundtrack. Create vertical, square, or other delivery versions from that master instead of rebuilding the performance for every destination.
This also makes later changes easier. A caption, crop, or cover image should not require regenerating a character that already works.
Use higher resolution to improve an approved result
Once both identities and the sequence are correct, inspect hair edges, faces, hands, clothing detail, and compression at the intended display size. More detail is useful when it survives delivery and improves what viewers see.
Do not use sharpness to compensate for a broken casting decision. A crisp but incorrect face remains incorrect. Likewise, an upscale cannot recover a second performer that was never replaced properly.
Inspect the actual exported file
Review duration, dimensions, audio alignment, watermark, first frame, and ending. Check for duplicated moments or abrupt holds introduced while assembling clips.
The editor preview is not the final deliverable. The complete exported file is the version that should pass the quality check.
17. What determines the cost—and what “free” means
There is no single price for “a Raindance AI video” because the phrase covers different deliverables. A short watermarked preview, a finished duet with sound, and a manually refined multi-shot remake are not the same purchase.
The main cost drivers are duration, generation quality, the number of revisions, preparation work, and finishing. Some tools package those into one template price; others charge separately for the stages.
| Cost component | What to check |
|---|---|
| Initial generation | The actual duration, quality, and number of subjects included |
| Reference preparation | Whether extra character views or edited frames are necessary |
| Revisions | Whether visual corrections consume additional credits |
| Finishing | Music, assembly, upscaling, and clean export |
| Plan terms | Subscription renewal, credit expiry, watermark removal, and download access |
Compare finished results rather than headline prices
A cheap generation is not good value when it consistently produces an unusable duet. Conversely, a more expensive model is not automatically justified when a simpler template already meets the brief.
A useful planning measure is the total production spend divided by the number of finished videos that are acceptable. Include revisions and finishing rather than counting only the first render.
For example, five hypothetical $1 attempts yielding one usable result cost $5 per usable video. Two hypothetical $2 attempts yielding one usable result cost $4. This illustrates the calculation; it is not a performance estimate for any named model.
Read the complete free offer
“Free” may refer to access to an editor, a limited allowance, a preview, or a watermarked download. Before uploading, check whether the allowance covers the desired duration, two references, and a usable export.
Also distinguish a failed generation task from a completed video with disappointing visual quality. Refund and retry rules may treat them differently. The relevant promise is what the product will deliver, not simply whether its page contains the word “free.”
18. Publishing a version people can understand
A clear creative idea benefits from a clear presentation. The following are editorial suggestions, not promises of reach or algorithmic preference.
Make the pairing readable
Show enough of both characters for the relationship or joke to register. When the concept depends on the second subject, do not hide that subject until an abrupt ending or crop it out of the opening shared shot.
A brief input-photo reveal can provide context, but it should not consume the entire payoff. The performance is the result viewers came to see.
Let the caption explain the idea, not the software
A caption such as “Our two original mascots in a Raindance-inspired duet” explains both the pairing and the artificial production. A vague claim of “the most realistic AI ever” supplies less useful context and invites a comparison the video may not support.
Use names and terms that accurately describe the clip. Do not label an unrelated rainy-street animation as a faithful remake of the original music video simply to attract the same search.
Present examples honestly
A before-and-after comparison should show the actual inputs used for the displayed result. A community inspiration clip should be credited as inspiration, not presented as an output of a different tool.
That distinction helps viewers understand the creative process and makes demonstrations more useful. Showing a complete shared shot is especially important when the claimed effect is replacement of two people.
Finish on a moment, not a technical limit
Trim or structure the edit around a completed action, a shared image, or an appropriate musical phrase. A maximum generation length is a production constraint, not an artistic ending.
A deliberately composed final moment can make a short version feel complete and give a longer version a reason to exist.
19. Consent, privacy, music rights, and AI disclosure
A convincing synthetic performance needs responsible handling precisely because it can make someone appear to have participated in a scene they never filmed. The following is general guidance, not jurisdiction-specific legal advice.
Obtain permission for the intended use
Use photographs of people who have agreed to the project and understand whether the result will remain private, be posted publicly, or promote a product. Treat the photograph, the depicted person, the source footage, and the soundtrack as separate permission questions.
For professional or commercial distribution, obtain advice appropriate to the relevant markets and licenses. Paying for a generation service does not establish that every third-party input is cleared.
A short excerpt is not automatically cleared
The U.S. Copyright Office distinguishes a musical composition from a sound recording. Permission relating to one should not be assumed to cover the other.18
It also explains that there is no fixed number of words, musical notes, or percentage of a work that automatically qualifies as fair use. A fifteen-second or twenty-eight-second duration is therefore not a universal exemption.19
Check whether the chosen music is authorized for the intended destination and use, especially for ads, client work, or downloadable templates. Attribution and an AI label do not replace permission.
Review how uploads are handled
Before submitting personal photographs, read the service’s current information about storage, deletion, public examples, third-party processing, and training or improvement uses.
Avoid uploading sensitive images unnecessarily. Do not publish private reference links inside tutorials or behind-the-scenes screenshots. A private-looking upload screen is not itself a statement about retention or deletion.
Use the appropriate disclosure controls
YouTube requires disclosure when AI meaningfully alters or generates photorealistic content, including making a real person appear to do something they did not do. Its guidance distinguishes that from non-realistic or minor edits.20
TikTok has also publicly described requirements to label realistic AI-generated content and the use of provenance information for automatic labels. Apply the current controls relevant to the destination and the kind of video being posted.21
Avoid implying that the original artists, a depicted person, or a character owner endorsed the remake. Transparency explains the nature of the video; it does not settle ownership or licensing.
20. What the trend reveals about AI video
Raindance is useful to understand beyond this particular song. It illustrates a broader creative shift from generating an isolated image of someone to placing a recognizable character inside a coherent performance.
The difference is substantial. A portrait can be judged in one frame. A performance requires identity, movement, interaction, timing, and continuity to work together. The audience is not only asking whether the character looks right; it is asking whether the character convincingly belongs in the scene.
The model approaches discussed here point toward several complementary forms of control: reusable character references, structural guidance, conversational revision, and edited-frame direction. The industry significance is not that one of them makes all the others obsolete. It is that creators can increasingly separate decisions about cast, action, and visual treatment instead of rebuilding everything together.11101416
For creators, that suggests a durable skill: learn to specify the performance that matters, the appearance that must remain recognizable, and the parts of the scene that may change. Those decisions transfer to other music-video remakes, character performances, and short narrative formats.
For viewers, the distinction will increasingly be between a technically surprising clip and a well-directed one. A complete, readable interaction can remain valuable after the novelty of substitution fades.
That is an interpretation of the technologies and examples, not a forecast of this trend’s future traffic. The lasting creative opportunity is the combination of familiar performance and deliberate new casting.
21. Frequently asked questions
What is Raindance AI?
It is a visual-remake trend associated with Dave and Tems’ “Raindance,” especially its waterfront performance. Creators place new people or characters into the roles, or generate a new scene inspired by that format.1
Which song is used?
The original recording is “Raindance,” credited to Dave and Tems. It appears on The Boy Who Played the Harp. Use the musical passage associated with the chosen edit rather than automatically starting at the beginning of the song.3
Is Raindance AI one official app?
No single app defines the format. Templates, general video editors, and multimodal generation systems can all produce versions. Their inputs, output lengths, and degree of source preservation can differ.
Who started the AI-remake trend?
The cited material does not establish a verified first creator. The original recording and official video have documented release context, but those dates should not be confused with the origin of a later AI format.
Is fifteen seconds better than twenty-eight seconds?
Choose the length that completes the idea. Shorter and longer published examples exist, but the available evidence does not establish that one duration is universally more popular or more effective. Keep both characters’ contributions and a satisfying ending.
Do the two people need to be in the same photograph?
No. Published two-person templates accept separate photographs. The important requirement is that each reference is associated with the intended role.8
Can I use only one photo?
Some templates use one subject for both roles; others keep an original performer or generate a partner. Check the stated behavior. To cast two specific, different subjects, use a separate approved reference for each.
Can two subjects with the same gender presentation play the roles?
The source roles and the replacement appearances are separate decisions. Assign each reference to the intended original performer rather than using gender to decide the upload order. Confirm that the selected tool supports the desired transformation.
Can I use pets, robots, or cartoons?
Published examples include nonhuman and stylized characters.27 These require more than a facial edit: anatomy, proportions, materials, and the interpretation of the performance all matter. A human-recasting demonstration does not establish equal support for every character type.
Is this face swapping or full-character replacement?
It can be either. Face-focused substitution largely retains the original body and outfit. Full recasting changes the broader appearance or character design. Decide which result you need before choosing a tool or evaluating a preview.
Will the video keep the clothes in my photograph?
Only treat that as part of the expected result when the workflow and brief specify it. Supply references showing the relevant outfit. A tightly cropped portrait cannot define clothing that is not visible.
Which model is best for Raindance AI?
Match the workflow to the brief. Dedicated recasting is relevant to changing people while preserving a performance; multi-reference generation suits broader redesign; selective editors suit controlled revisions. The model comparison above explains the documented differences without treating them as a universal quality leaderboard.
Why does only one person get replaced?
The template may be designed for one role, the references may be ambiguous, or the system may not execute the two-person transformation reliably. Check the intended operation and both references, then judge the complete sequence rather than repeatedly adding stronger adjectives.
Why do the two characters switch roles?
The source assignment may be unclear or may have been interpreted inconsistently. Identify the original performers with stable distinguishing features and bind each reference to one role across the whole sequence, not to a changing screen position.
Does a longer prompt improve the result?
Only when the added detail resolves an actual ambiguity. Specify who replaces whom, what visual design to retain, and what should remain from the source. More text does not substitute for suitable references or a capable workflow.
Do I need a character sheet?
Not for every project. It can help when the whole design matters or the performance shows several angles. Review generated views carefully because unseen details are interpretations, not additional evidence of a real person’s appearance.
Will a higher-resolution version fix inconsistent faces?
Not necessarily. First approve identity, assignment, and continuity. Then use higher-resolution generation or finishing to improve visible detail. Sharpness and correct casting are different quality dimensions.
Does using my photo make the video sing in my voice?
No. Visual replacement, lip synchronization, and voice generation are separate functions. Confirm whether the output retains the original soundtrack, generates new sound, or uses an independently supplied recording.
Is there a completely free version?
Check the current offer for the exact result you need. A free editor, signup allowance, or watermarked preview is not necessarily a free finished duet at the chosen duration and quality. Review download and revision terms before generating.
Can I make it on a phone?
A mobile app or supported browser workflow can handle the process. The important checks remain the same: clear references, correct roles, a complete review, an appropriate crop, and an exported file with the intended sound.
Do realistic AI remakes need a label?
They may fall within the destination’s disclosure requirements. YouTube’s guidance explicitly covers realistic AI alterations that make people appear to do things they did not do; TikTok has also published realistic-AI labeling requirements.2021
Can the result be used commercially?
That depends on the tool’s terms and the rights in the photographs, likenesses, footage, music, and character designs. An export button or paid subscription is not proof that every component is licensed for advertising or redistribution.
22. The bottom line
A convincing Raindance AI video brings together recognizable casting, coherent performance, and a deliberate edit. Its quality is not determined by the newest model name, the longest duration, or the sharpest first frame.
Begin with the creative goal. Use a reference-preserving workflow for a close remake and a generation-led workflow for a new interpretation. Prepare references that define the intended subjects, assign the roles clearly, and review every appearance of both characters.
Then finish the video as a video: preserve the interaction, align the music, protect the composition, and give the sequence an ending. Handle the people and media involved responsibly.
The best result is not merely a familiar scene with different faces. It is a performance that feels coherent with its new cast.
Editorial basis
Model descriptions in this guide are grounded in official documentation; creator and template examples are attributed to their publishers. Task-fit assessments are editorial analysis, not a claim of hands-on benchmarking or measured success rates. Product capabilities can change, and selected social examples do not establish market-wide popularity.
Sources
Footnotes
-
Raindance AI Video, What is the Raindance AI video trend?. A product-authored explanation of the trend and the distinction between reference-led and original-scene workflows. ↩ ↩2 ↩3 ↩4
-
Ala Kallala, Recreate the Dave & Tems Raindance Trend with Higgsfield Genjutsu. A creator-authored account with character references and a generated example. ↩ ↩2 ↩3 ↩4
-
Apple Music, The Boy Who Played the Harp. Album release date, recording credit, and track duration. ↩ ↩2 ↩3 ↩4
-
Universal Music Canada, Dave Shares Official Video for “Raindance” ft. Tems, January 9, 2026. Official video announcement, filming location, and original-video link. ↩ ↩2
-
Official Charts, RAINDANCE — DAVE/TEMS. Official Singles Chart history, checked October 7, 2026. ↩
-
Starrd, How to Make the Dave & Tems “Raindance” AI Video, October 5, 2026. A publisher-described 28-second template and depth-guided production process. ↩ ↩2 ↩3
-
Hotel Lobby AI, Raindance AI community examples. Third-party labels for Tyler’s community remakes; the page distinguishes those examples from its own generated outputs. ↩ ↩2 ↩3
-
Nsketch, Rain Dance template. A two-photo interface with a stated 15-second length. ↩ ↩2 ↩3
-
MiniMax, MiniMax H3 model card. Official system overview, reference modalities, generation specifications, and workflow components. ↩ ↩2 ↩3
-
ByteDance Seed, Seedance 2.5. Official overview of longer generation, reference control, structural guidance, and editing. ↩ ↩2 ↩3
-
Kling AI, Kling VIDEO 3.0 Omni Model User Guide, February 6, 2026. Official character-element, multimodal-reference, and storyboard guidance. ↩ ↩2 ↩3 ↩4
-
ByteDance Seed, One-take Creation, Flexible Referencing: Introducing Seedance 2.5, July 31, 2026. Official release explanation, capabilities, examples, and stated limitations. ↩ ↩2
-
H3 Max Recast documentation, published by fal. Specification of the named recasting workflow, including photographs, source limits, assignments, and retained sound. ↩ ↩2 ↩3
-
Google DeepMind, Gemini Omni. Official descriptions of multimodal creation, reference-guided edits, and conversational revision. ↩ ↩2 ↩3
-
Higgsfield, Meet Higgsfield Genjutsu: How It Works and What You Get. Official distinction between Motion Transfer and Object Swap. ↩ ↩2
-
Runway, Aleph 2.0. Official description of edited-frame guidance, selective editing, multi-shot changes, and supported clip length. ↩ ↩2 ↩3 ↩4
-
Lihe Yang and collaborators, Depth Anything V2, NeurIPS 2024. Primary research on monocular depth estimation, including the distinction between an image-based method and video demonstrations. ↩
-
U.S. Copyright Office, Musical Compositions and Sound Recordings. Explanation of the distinct copyrighted works. ↩
-
U.S. Copyright Office, Fair Use FAQ. Contextual assessment and the absence of a fixed automatically permitted amount. ↩
-
YouTube Help, Disclosing use of GenAI content. Disclosure guidance for meaningful photorealistic alterations and generated content. ↩ ↩2
-
TikTok Newsroom, Partnering with our industry to advance AI transparency and literacy, May 9, 2024. Published explanation of realistic-AI labeling and provenance initiatives. ↩ ↩2
Author
Categories
More Posts
Raindance AI Photo Guide: Prepare Two Portraits
Photo requirements and a practical guide to choosing the duet singer.
How to Choose the Singer in a Raindance AI Video
Understand the Photo 1 default, choose either person as the singer, and prepare portraits that are easy to recognize.
Raindance AI Video Specifications
Reference and finished video duration, frame composition and output resolution.